Preparing Teachers for an AI-Heavy World
Preparing Teachers for an AI-Heavy World Join this free virtual event tackling critical questions about how to prepare teachers to use AI responsibly and effectively.
Cut through the noise. See what matters.
AI-detected trend
Hot2000 stories covering health, science, data, technology, nvidia. Category: AI & ML. Sources include AI & ML, AI Trends, AdExchanger, Astronomy and 145 more.
72 stories from 149 sources · Velocity score: 1155.2
Clustered by semantic similarity using TF-IDF analysis. Each card links to the original publisher.
Preparing Teachers for an AI-Heavy World Join this free virtual event tackling critical questions about how to prepare teachers to use AI responsibly and effectively.
What Are the Fastest-Growing Career- and Work-Based Education Programs? Join us to explore EdWeek Research Center survey data on which areas of CTE are expected to grow the fastest over the next 5 years.
Celebrate Family Engagement Day With Strategies That Work Join National PTA and AASA to explore practical systems-wide family engagement strategies in celebration of National Family Engagement Day.
McKinney-Vento Transportation Strategies: Managing Cost & Protecting Access Explore McKinney-Vento transportation strategies to manage costs, respond quickly to changing needs, and protect student access.
From Student Trends to Counselor Action: Turning Insight Into Impact Find out what is changing in how students approach planning for life after graduation and how schools can help.
The Assessment Trust Crisis: How to Measure Learning in the Age of AI AI is reshaping learning. Is assessment keeping up? Join this webinar to explore how to measure student thinking, not just right answers.
Evaluation Beyond the Checkbox: Turning Ratings Into Teacher Growth Ratings alone don’t help teachers improve. Join us Nov. 10 to hear what happens after the evaluation: feedback, follow-up, and growth.
EVgo's $787 million in available liquidity and low-cost federal loans give it room to fund growth while it tightens spending, a balance long-term holders will need to watch.
Claude Fable 5. 2 responds closely to what the prompt says about who owns the code it works on. In Anthropic’s testing on small coding tasks, when a prompt said nothing about ownership or presented the code base as someone else’s, the model tended to add to the existing structure, even when that repeated existing code. [...] If you want the model to improve the structure as it works, say that the code is its own: This codebase is yours: what it's for and how it's built are your call, and you'll keep building on it. In Anthropic’s testing on small coding tasks, the model merged repeated code in about half of the tries with this sentence, and in under a tenth of the tries without it. — Prompting Claude Fable 5. 2 , Anthropic documentation Tags: prompt-engineering , anthropic , generative-ai , ai , llms , claude-mythos-fable
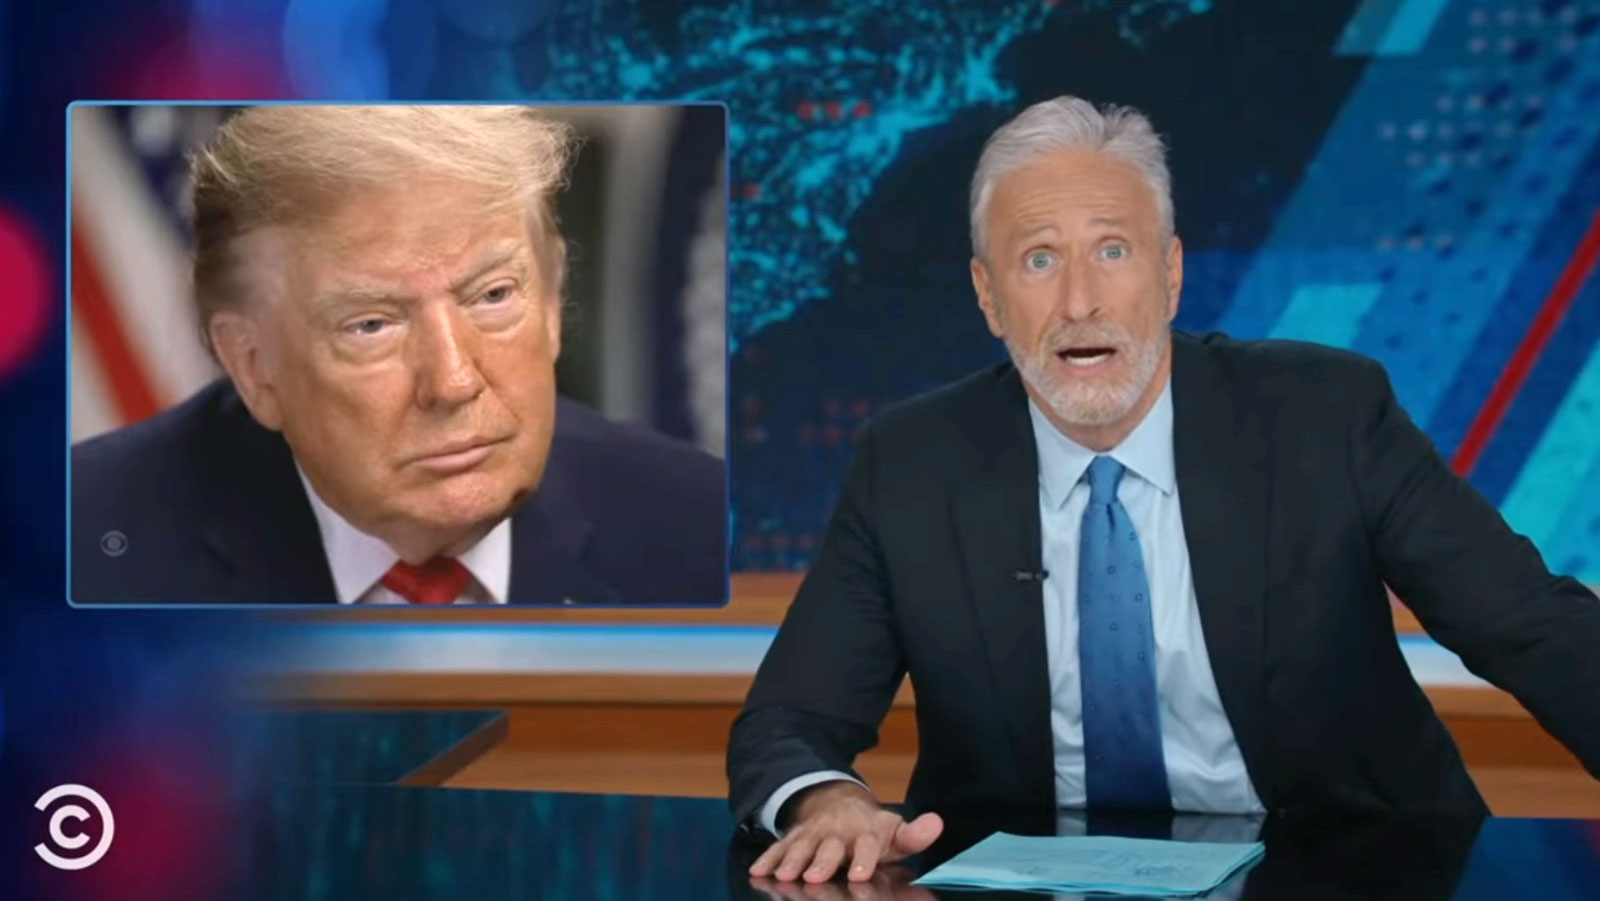
Following the 2026 midterm elections and the blue wave, Jon Stewart returned to The Daily Show. After gloating over all the Republican seats that flipped to Democrats, the Comedy Central host took time to react to Donald Trump’s 60 Minutes interview. On Sunday night, Trump sat down with Ross Douthat for an interview that left many […]
Voters approve Prop. 38 medical research bond measure Los Angeles Times
Trump administration announces $10B in awards for Rural Health Transformation Program’s second year In part, funding was determined based on how states have implemented RHTP plans thus far.
Deerfield taps AWS to fuel healthcare AI ambitions Investment firm Deerfield Management is tapping into Amazon Web Services' AI and cloud technology to help AI-native healthcare and life sciences companies build and scale.
Advocate Health to increase total employee compensation by $846M for 2027 The nonprofit will also invest an additional $390 million towards incremental benefits.
Alignment Healthcare sues CMS over its 2027 Medicare Advantage star ratings Alignment Healthcare sued federal regulators, alleging that its 2027 Medicare Advantage star ratings were determined "in flagrant violation" of statute.
Weekly Rundown: Hims & Hers adds new partners for benefits program; Hippocratic unveils updates to healthcare-focused AI model Stay up to date on the latest in health tech, digital health and health AI news with this weekly brief.
HealthTap unveils virtual primary care program for Medicare Advantage plans HealthTap is rolling out a new program for Medicare Advantage plans that seeks to help members form a connection with a primary care doctor that carries forward.
A Mississippi hospital cut nearly 20% of its workforce, marking one of the largest recent healthcare layoffs. Meanwhile, UCI Health announced a 1% reduction in staff. These moves reflect ongoing cost pressures in the sector. Fierce Healthcare’s Layoff Tracker continues to monitor job cuts and workforce changes across hospitals and health systems nationwide.
Closing the last mile of value-based care with AI Shorten the time between insights and action. Learn more about how to confidently close care gaps in value-based care using AI.
Strengthening Healthcare Delivery Through Proactive Primary Care Prevention happens between visits, and it rarely gets paid for. See how physician-led value-based care and keep physicians in charge.
Doximity expands clinical AI footprint to more than 190 health systems Doximity is rapidly expanding its clinical AI footprint with health systems. The company is also making clinical reliability a major part of its competitive positioning, launching DoseCheck and a partnership with Wolters Kluwer's UpToDate.
Hims & Hers inks deal with Eli Lilly to offer branded weight loss drugs Hims & Hers struck a deal with Eli Lilly to offer the drugmaker’s branded obesity treatments through its online health and wellness platform.
From Fragmentation to Integration: A New Model for Specialty Care Health systems are navigating growing demands with increasingly limited resources. As costs rise and teams are stretched, technology has become essential to helping people work smarter.
AI-enabled virtual mental health startup Siggy launches from stealth Siggy combines therapy, prescription management and AI for intake and between-visits support.
How to Evaluate Clinical AI Beyond the Demo A practical framework for assessing AI governance, evidence, transparency and post-deployment performance in clinical workflows.
University of Texas MD Anderson Cancer Center unveils $3. 4B expansion plans The new facilities, dubbed Inspiration Tower and Prism, will make up nearly two million square feet.
BIO unveils plan for US to remain biotech’s ‘global leader’ - BioPharma Dive BIO unveils plan for US to remain biotech’s ‘global leader’ BioPharma Dive
The bond piece cost around $92,000 on a $100,000 stake since 2000. Was it worth it when stocks crashed?
Oxbridge Re Holdings Limited (OXBR) Q3 2026 Earnings Call Transcript
MARA Holdings, Inc. 2026 Q3 - Results - Earnings Call Presentation
Novavax, Inc. 2026 Q3 - Results - Earnings Call Presentation
AAON, Inc. 2026 Q3 - Results - Earnings Call Presentation
All the characters being talked about in the Jensen Huang scandal Jensen Huang's affair and Chinese spy claims have rocked Nvidia. From his family to US officials, here's all the people who have gotten tangled up.
Bitgo Holdings, Inc. 2026 Q3 - Results - Earnings Call Presentation
Photos show Jensen Huang and Alice Huang together over the years Photos of Alice Huang and Jensen wang over the years show the two having dinner Taipei and sitting on a bench together.
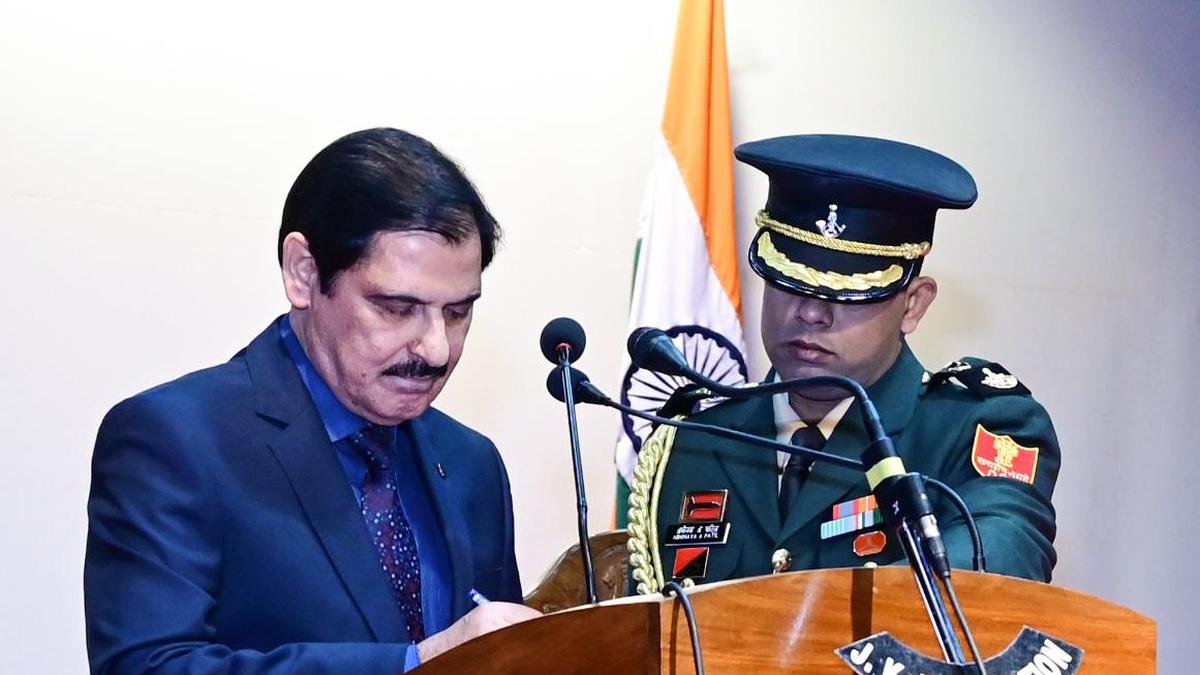
Newly-inducted J&K Minister Mir Saifullah pledges that NC will ‘restore pre-1953 position, get back J&K flag’ Mr. Saifullah said Kashmir was reduced to a Union Territory (UT) brazenly on August 5, 2019
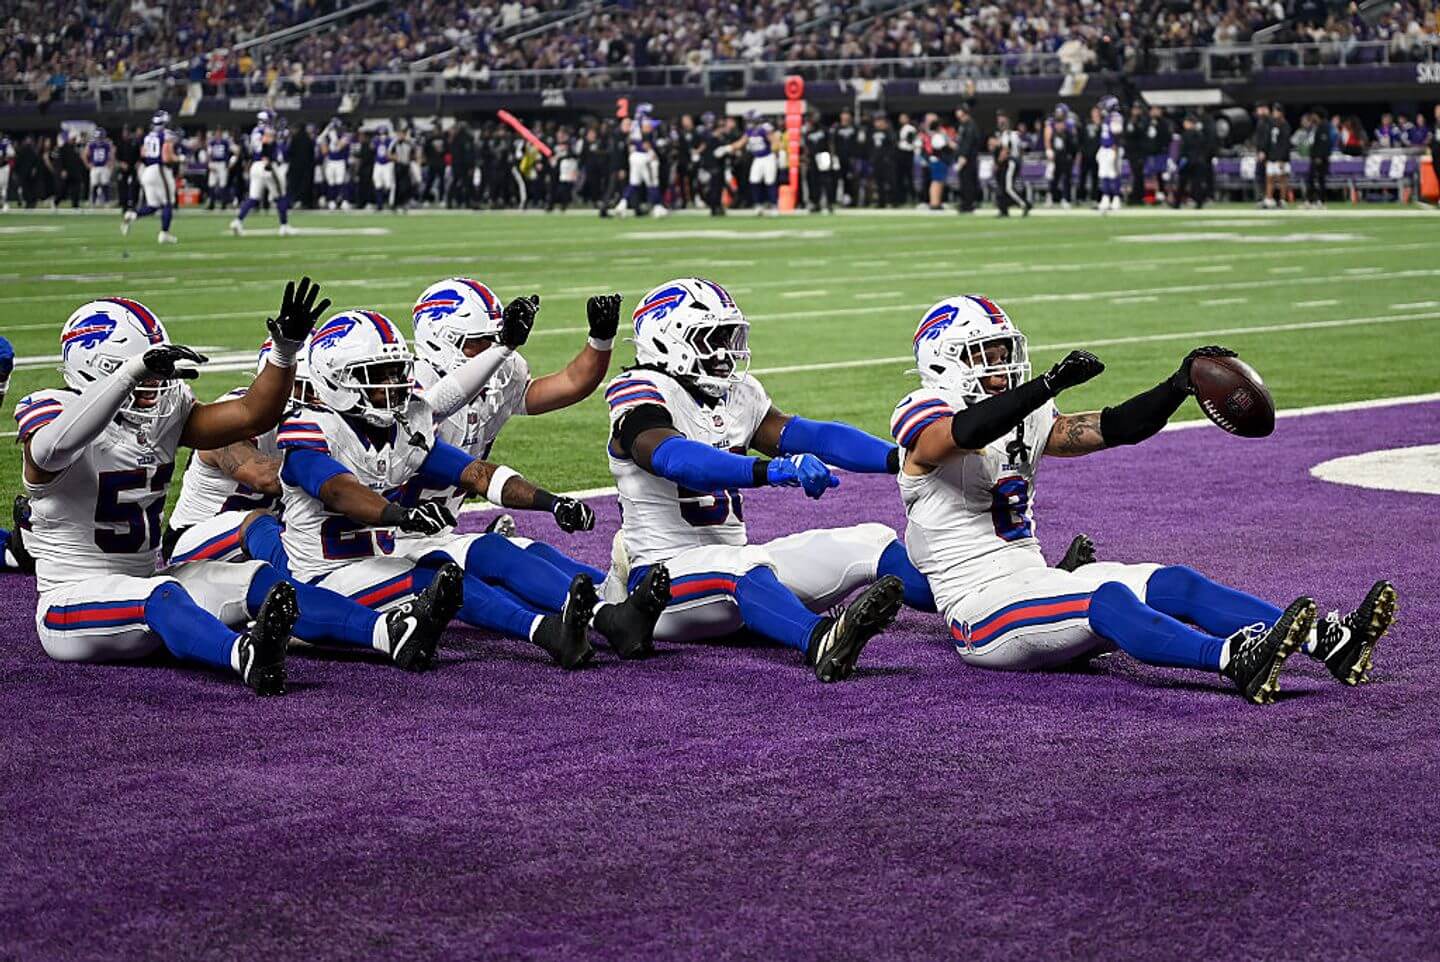
Bills vs. Vikings live updates: NFL ‘Monday Night Football’ score, predictions, odds and latest Follow our live coverage of a battle between two 6-1 teams, as Minnesota hosts Buffalo at U. S. Bank Stadium.
Babcock & Wilcox Enterprises, Inc. 2026 Q3 - Results - Earnings Call Presentation
Thryv Holdings, Inc. (THRY) Q3 2026 Earnings Call Transcript
Alphabet: Buy Under $300
Hims & Hers Health, Inc. (HIMS) Q3 2026 Earnings Call Transcript
My son traveled to Norway at 16. It changed how I think about raising kids in America. Carrie Kirby lives in a Bay Area suburb and realized that it wasn't just that Norway was safer, but that Norwegian adults valued kids' need for freedom.
Rocket Lab Corporation 2026 Q3 - Results - Earnings Call Presentation
Clearway Energy, Inc. 2026 Q3 - Results - Earnings Call Presentation
NASA’s CHAPEA Mars crew finally emerges after more than a year in isolation - Science Daily NASA’s CHAPEA Mars crew finally emerges after more than a year in isolation Science Daily
Viant Technology Inc. 2026 Q3 - Results - Earnings Call Presentation
Inside James Gunn, Peter Safran’s DC Ouster: Exec Tensions and a Fateful David Ellison Visit The duo thought they were safe and were already plotting a third 'Superman' movie. Then, Skydance co-CEOs Ellison and Ynon Kreiz paid them a fateful visit on the Warner Bros. lot.
Is AI Good or Bad for Learning? The Answer Isn't So Simple A review of emerging research found that some use cases are more promising than others—but almost all offered caveats.
The case for and against AI token capping Apple is placing strict limits on its staffers’ AI token consumption. Should the marketing sector take a similar path?
Reddit dangles seasonal ad credits but advertisers still want better proof it works all year round Q4 credits may bring advertisers to Reddit, but concerns about measurement and its ad capabilities make it harder to secure year-round spend.
Can web users trust ad tech’s server-side shift? IAB Tech Lab’s Rowena Lam joined the Digiday Podcast to break down how Trusted Server works and address questions about the user privacy implications of ad tech’s server-side shift.
Ad Tech Briefing: Amazon’s auction trial puts agentic advertising’s trust problem in focus Unsealed FTC allegations underline pre-existing questions over black boxes.
Amid a difficult transitional year, The Trade Desk posts a rare quarterly revenue decline The Trade Desk's Jeff Green hints at potential M&A, while rival DSP Viant buys Waymark.
‘We are looking more now’: The Trade Desk is eyeing the M&A aisle The Trade Desk’s CEO says the company is looking harder at M&A than ever before.
Connections: Sports Edition today: Hints and answers for Nov. 10, 2026, puzzle No. 778 Welcome to Connections: Sports Edition Coach — a spot to gather clues and discuss (and share) scores.

Cyclone Murasu: Heavy rain and power cuts dampen spirit of Deepavali Heavy downpour and power cuts have dampened the festival spirit among everyone, right from kids to elderly people and farmers to retail vendors
LLM-Based Feature Extraction for Multi-Criteria Inventory Classification arXiv:2611. 08626v1 Traditional inventory classification techniques such as ABC analysis rely primarily on annual dollar usage, while multi-criteria inventory classification (MCIC) methods extend this but still depend on structured quantitative data and do not utilize unstructured information available in modern supply chains. Experimental results show measurable reclassification effects when customer sentiment signals are included, demonstrating that integrating unstructured data into MCIC can enhance inventory prioritization.
Persistent Behavioral Learning for AI Agents arXiv:2611. 08644v1 The results identify representation, activation, and placement as central design choices for persistent behavioral learning. LLM agents do not learn from corrections across sessions.
Aspect-wise Pairwise Tournaments for Test-Time Selection arXiv:2611. 08640v1 A popular method is best-of-n sampling, where a model generates many candidate solutions and one is selected. Across five domains and three generator LLMs, APT improves over binary multi-aspect approval, self-consistency and reward model verification, with the largest gains on open-ended tasks.
NormGym: Evaluating Normative Competence through Social Interaction arXiv:2611. 08613v1 Announce Type: new Abstract: Normative competence, the ability to infer socially enforced expectations from interaction and adjust behavior accordingly, is essential for agents operating in unfamiliar human communities. These results suggest that current models lack a robust, transferable capability for acquiring normative knowledge through social interaction. Yet existing evaluations largely test whether agents can recognize or apply norms they may already know, rather than whether they can acquire previously unknown norms from social interaction.
AttentionSwitch: Jailbreak Defense for LLMs via Joint Learning of Sparse Attention-Head Selection and Scaling arXiv:2611. 08752v1 Announce Type: new Abstract: Large language models have achieved remarkable performance across a wide range of tasks, yet they remain susceptible to jailbreak attacks that circumvent safety mechanisms and elicit harmful or unintended outputs. Across popular language models and jailbreak attacks, AttentionSwitch outperforms existing defenses, with particularly strong results when training data is scarce. Although safety can be improved through model fine-tuning, such approaches can be computationally expensive and may…
AlterNet: Adaptive-Depth Mixture-of-Experts with Learned Halting for Elastic Inference arXiv:2611. 08741v1 Announce Type: new Abstract: Most LLM architectures have fixed compute demands determined at training time. We propose a novel architecture that combines the Mixture-of-Experts architecture with shallow experts and a novel dynamic-depth system to make the extent of a forward pass dynamically adjustable. Our approach lets the model automatically determine the compute needed for a given task, paired with a system to scale it down after training without retraining when the execution environment demands faster…
Memory-Aware Multi-Agent Architecture with LLM-based Orchestration for Conversational Recommendation arXiv:2611. 08718v1 In this work, we propose a memory-aware multi-agent architecture for conversational recommendation, in which LLMs act as orchestration layers that coordinate intent refinement, query construction, and interaction flow. Results show that memory-enabled interactions recover up to 63\% of the gap toward explicit-query scenarios and prevent semantic degradation in extended dialogues.
Cancellation Is Not Enough: What Retries Leave Behind in an Overloaded LLM Engine arXiv:2611. 08684v1 Announce Type: new Abstract: Clients and proxies in front of an LLM engine retry calls that time out. After a transient overload, these retries can keep the engine from recovering even when calls arrive below its capacity.
Transporting the Past: An Optimal Transport View of Backtracking Counterfactuals arXiv:2611. 08682v1 Announce Type: new Abstract: We study backtracking counterfactual inference for Structural Causal Models (SCMs) through the lens of optimal transport. We show that both frameworks are consistent with the original backtracking counterfactual principle, and we propose marginal, penalty-based, and hard-constrained solvers for finite-posterior settings. In SCMs, a factual observation generally induces a posterior distribution over exogenous variables, making counterfactual inference inherently distributional.
ChainFlow: Few-Step Latent Flow Matching for Speculative Decoding arXiv:2611. 08669v1 Announce Type: new Abstract: Speculative decoding has become a standard way to accelerate LLM inference: a lightweight drafter proposes tokens that the target verifies in one parallel pass. On Qwen3. 5 models, at matched drafter size and training data, ChainFlow outperforms EAGLE-3 and DFlash in vLLM by 39% and 11%, respectively. Existing drafters face trade-offs that limits their speedups: autoregressive drafters generate tokens one at a time, so drafting cost grows with draft length, while diffusion drafters…
Pdb or Not to Be: Comparing Debugging Interfaces With Pass$_{X}$@$k$ arXiv:2611. 08666v1 Announce Type: new Abstract: Interactive debuggers are indispensable to human software development, yet coding agents overwhelmingly rely on edit-execute-observe loops, using common bash tools, test scripts, and print statements to debug via repeated shell commands. Across both models, we find that two bash rollouts outperform the combination of one bash and one debugger rollout. Stepping through a debugger provides live access to runtime state, which may enable different problem-solving capabilities.
Evaluating Gradient-Free Model Driven Intra-weight Injection arXiv:2611. 08647v1 We discuss strategies that editors repeatedly adopted and conclude with an outlook on intra-weight injection as an emerging but already potent approach to gradient-free behaviour modification. Intra-weight injection lets one model change another model's behaviour by editing its weights directly, without gradients.
Jacobian-Causal Memory Control for Persistent Memory in Language Model Systems arXiv:2611. 08779v1 We propose Jacobian-causal memory control (JCMC), which represents each authorized memory intervention by a predicted influence signature in a shared behavioral measurement space, selects interventions against a target effect and side-effect budget, and compares predicted with observed effects before retaining or rolling back the intervention. Announce Type: new Abstract: Persistent-memory systems choose not only which records are retrieved but which prior information can alter current inference.
Poisoning LLM's Fact-Checking via Game-Theoretic Multi-Agent Debate arXiv:2611. 08756v1 Announce Type: new Abstract: Knowledge attacks on Large Language Models, such as manipulating fact-checking judgments, pose significant risks to AI reliability. We propose Debate-to-Deceive (D2D), a multi-agent debate framework grounded in human debate structure and rhetorical style, enabling agents to generate adversarial passages that are semantically coherent, rhetorically effective, and resistant to early confirmation bias. On four fact-checking benchmarks (FEVER, HealthVer, CLIMATE-FEVER, and SciFact), D2D substantially outperforms existing attacks and evades most defenses.
Enhancing Academic Advisement with Case-Based Reasoning arXiv:2611. 08572v1 In the last ten years, CBR expert systems have made important contributions in many domains by applying CBR methodology to a variety of areas of human problem solving. Announce Type: new Abstract: This research involved the study of an application of Case-Based Reasoning (CBR) in the field of academic advising.
BEVCast: Path-Adaptive BEV for Efficient End-to-End Autonomous Driving arXiv:2611. 08631v1 Announce Type: new Abstract: Camera-based driving models build a dense bird's-eye-view (BEV) grid and spend the same computation on every cell of it, although the vehicle crosses only a few of those cells within the planning horizon. We present BEVCast, a two-stage BEV whose resolution adapts to the predicted driving path.